

自动驾驶-M2 感知与 BEV-2.1 CARLA 多相机数据采集-标注不完整(3)
标注问题
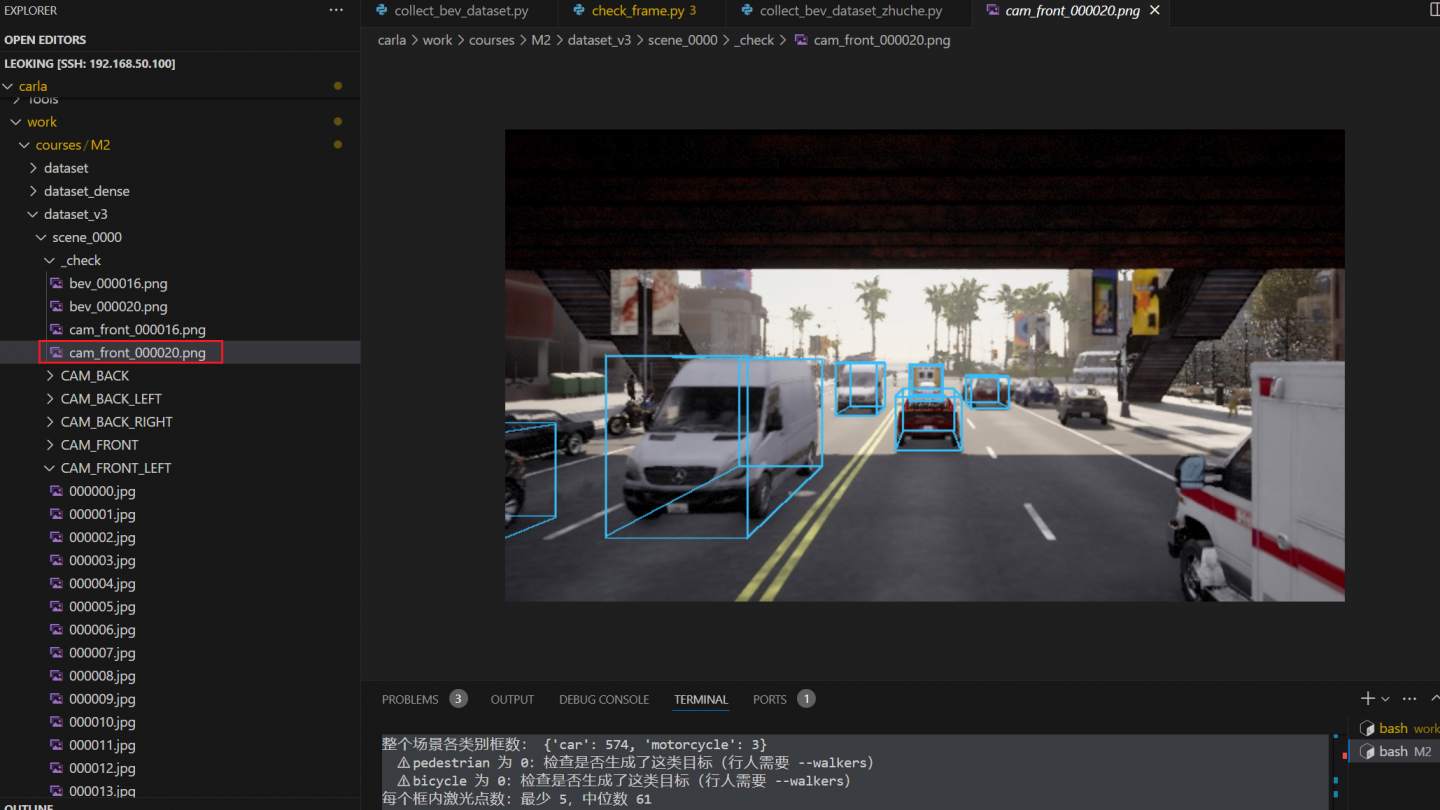
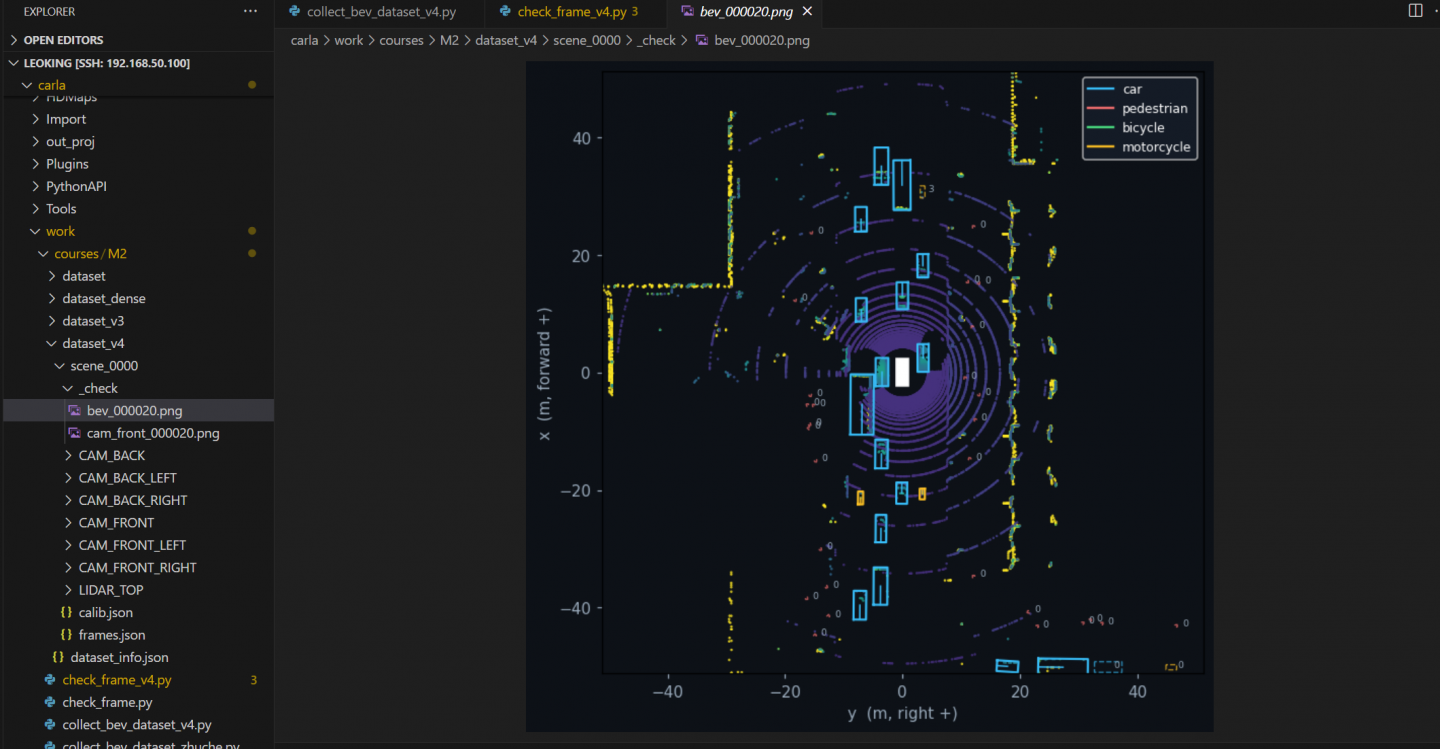
车的部分已经很好了:Town10HD 的车流集中到了自车周围,鸟瞰图里有 15 个左右的框,前视图里 15–40 米处的几辆车,框都贴得很准。但图里暴露了 3 个问题,前两个我已经修好(v4),第三个需要你再跑一次才能定位。
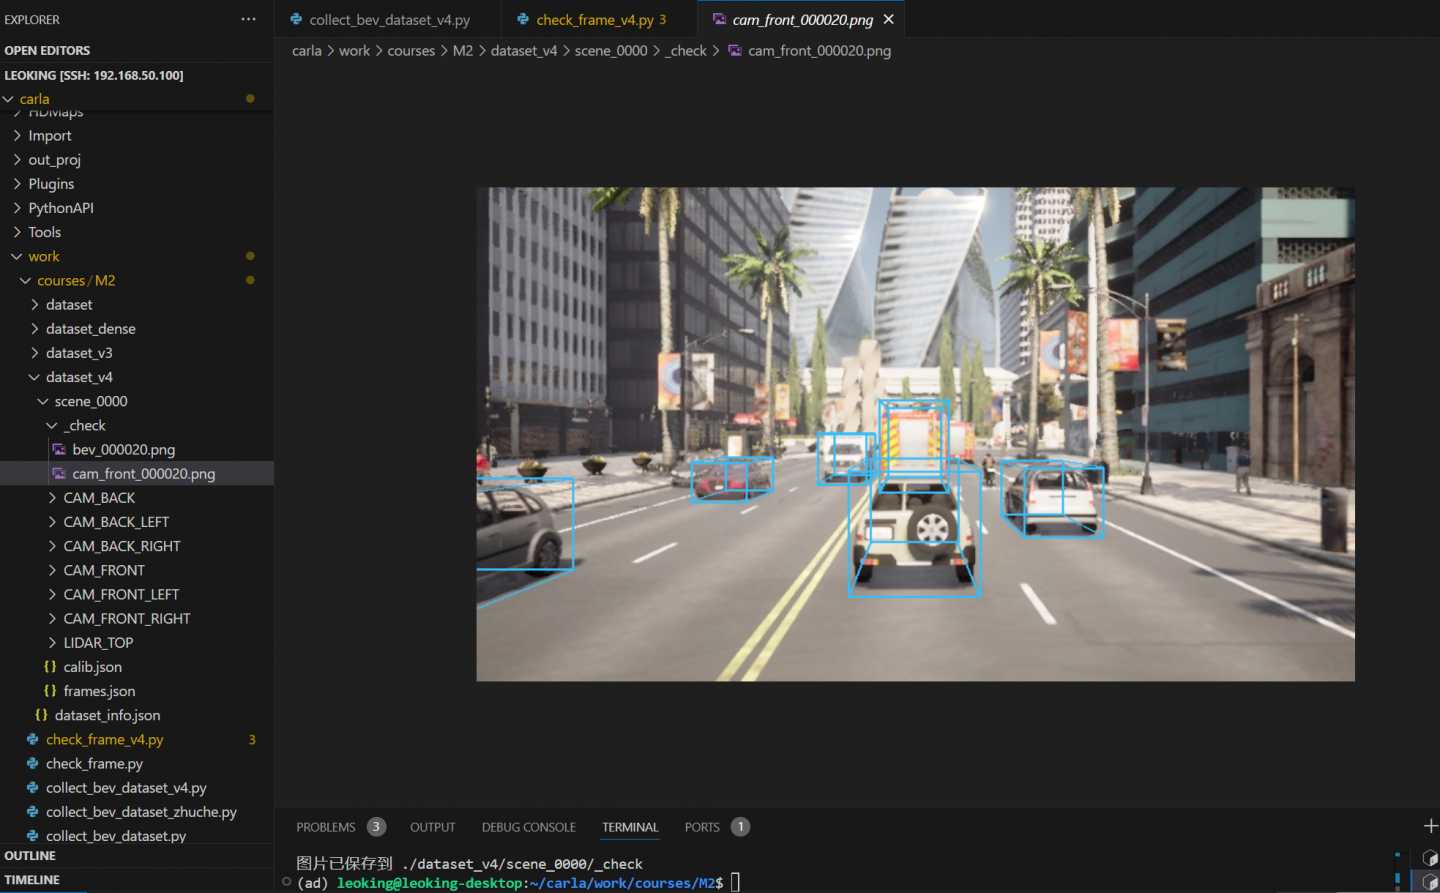
问题 1:右边那辆救护车没有框
它其实已经被标注了。 鸟瞰图里自车右前方(x≈3,y≈+4)那个框就是它。没画出来,是 check_frame 的问题:救护车贴着自车,框有一半在相机背后,旧版遇到这种情况就整个跳过不画。新版会把框在相机前方 0.3 米处截断,只画能看见的部分。我用假数据测过,贴身的大车能正常画出来了。
问题 2:一辆摩托和自行车都没有,van 左边那辆骑手也没框
这是 CARLA 自身的 bug。CARLA 0.9.14/0.9.15 里两轮车的 bounding box 是坏的,宽度几乎为 0。有论文专门写过:用这个版本做数据集时,自行车和摩托的框投影出来是"一条线",所以他们干脆把两轮车排除了。
宽度为 0 的框里永远数不到 5 个激光点,所以全部被我们的过滤规则丢掉了。v3 确实按 25% 的比例生成了两轮车,但它们一个都没进标注。这点是我上一版没有预料到的。
v4 的做法: 检测到这种"扁框"时,自行车改用 1.8×0.7×1.7 米、摩托改用 2.2×0.9×1.6 米的典型尺寸,框底放在地面上,并在标注里加一个 size_fixed: true 字段,说明这个尺寸是我们补的。
问题 3:行人还是 0,原因还需要测
可能有两种情况:
- 行人根本不在 51.2 米范围内;
- 行人在范围内,但激光点不够被过滤了。
为了不靠猜,v4 不再直接丢掉被过滤的目标,而是记进 frames.json 的 rejected 字段。采集结束时会按类别打印"保留 / 被过滤"的数量;鸟瞰图里被过滤的目标画成虚线框,旁边标着框内的激光点数。
请这样再跑一次
python collect_bev_dataset.py --scenes 1 --frames 50 --npc 60 --walkers 40 --towns Town10HD --out ./dataset_v4
python check_frame.py ./dataset_v4/scene_0000 --frame 20
然后把采集结束时打印的这张表贴给我:
    类别统计(保留 / 范围内但被过滤):
      car          ... / ...
      pedestrian   ... / ...
      bicycle      ... / ...
      motorcycle   ... / ...
怎么读这张表:
- 如果 pedestrian 是 0 / 0,说明行人不在范围内,问题出在生成位置上。
- 如果是 0 / 很多,说明行人在附近但激光点不够,问题出在过滤规则或者行人的框上。
- bicycle 和 motorcycle 的"保留"那一栏应该不再是 0。
两种情况的修法不一样,看到这张表就能确定是哪一种。
另外,前视图右侧远处还有几辆没框的车,在 40–50 米附近。v4 的鸟瞰图里,如果它们出现在虚线框里,就是激光点太少被过滤了,这符合"看不见的不标"的规则,属于正常现象。
写进学习笔记
用 CARLA 0.9.15 采集时,自行车和摩托的 bounding box 宽度接近 0,"框内激光点 ≥ 5"这条规则会把它们全部过滤掉。数据集里一个两轮车样本都没有,但不报任何错。
教训: 每个类别都要单独统计数量,总数看起来正常不代表每类都正常。量产数据闭环里叫"按切片评估",5.1、5.5 会反复用到。
这条比"我跑通了采集脚本"更有分量,面试时可以直接讲。
Sources:
V4 版本代码
collect_bev_dataset_v4.py
#!/usr/bin/env python3
# -*- coding: utf-8 -*-
"""
CARLA BEV 训练数据集采集

产出: 6 路环视图像 + 激光雷达点云 + 3D 框真值 + 标定 + 自车位姿

用法:
    # 单场景快速验证
    python collect_bev_dataset.py --scenes 1 --frames 50 --out ./dataset
    # 批量多场景采集
    python collect_bev_dataset.py --scenes 10 --frames 200 --out ./dataset

v2 修正(2026-10):
    1. 类别改用蓝图 base_type 属性判断(原版会把 vehicle.bh.crossbike 标成 car)
    2. 新增行人生成 --walkers(原版 pedestrian 类别永远为空)
v3:
    3. NPC 从主车附近的出生点往外放,并按 25% 比例混入自行车/摩托
    4. 行人只在主车周围 60 m 内生成
v4:
    5. 修正 CARLA 两轮车"扁框"(宽度≈0)导致自行车/摩托全部被过滤
    6. 被过滤的目标写进 frames.json 的 rejected 字段,结束时按类别打印保留/过滤数
"""

import argparse
import json
import math
import os
import queue
import random
from collections import Counter

import numpy as np
import carla

# ==================== 配置 ====================
IMG_W, IMG_H = 800, 450
FPS = 10

# BEV 感知范围(与训练配置保持一致,见本节说明)
PC_RANGE = 51.2

# 6 路环视布局(对齐 nuScenes 惯例)
CAMERA_RIG = {
    "CAM_FRONT":       {"x":  1.5, "y":  0.0, "z": 2.4, "yaw":    0, "fov": 70},
    "CAM_FRONT_LEFT":  {"x":  1.3, "y": -0.5, "z": 2.4, "yaw":  -55, "fov": 70},
    "CAM_FRONT_RIGHT": {"x":  1.3, "y":  0.5, "z": 2.4, "yaw":   55, "fov": 70},
    "CAM_BACK":        {"x": -1.5, "y":  0.0, "z": 2.4, "yaw":  180, "fov": 110},
    "CAM_BACK_LEFT":   {"x": -1.0, "y": -0.5, "z": 2.4, "yaw": -110, "fov": 70},
    "CAM_BACK_RIGHT":  {"x": -1.0, "y":  0.5, "z": 2.4, "yaw":  110, "fov": 70},
}

LIDAR_CFG = {"x": 0.0, "y": 0.0, "z": 2.5}

# 训练类别:car / pedestrian / bicycle / motorcycle
# [修正] 原版用蓝图名前缀判断,"vehicle.bicycle" 在 CARLA 里并不存在,
#        vehicle.bh.crossbike 会被误标成 car。0.9.14 起每个车辆蓝图都带 base_type 属性
#        (car / truck / van / bus / motorcycle / bicycle),直接用它最可靠。
BASE_TYPE_MAP = {"motorcycle": "motorcycle", "bicycle": "bicycle"}  # 其余(car/truck/van/bus)都归 car
DEFAULT_CATEGORY = "car"

# [v3] 让目标集中在主车附近,并保证各类别都有样本
TWO_WHEEL_RATIO = 0.25   # NPC 里两轮车(自行车+摩托)的比例
WALKER_RADIUS = 60.0     # 行人只在主车周围多少米内生成

# [v4] CARLA 0.9.14/0.9.15 的两轮车 bounding_box 是坏的(宽度接近 0,投影出来是一条线),
#      框里永远数不到 5 个激光点,会被全部过滤。检测到这种"扁框"时改用典型尺寸(半尺寸,米)
TWO_WHEEL_HALF_SIZE = {"bicycle": (0.90, 0.35, 0.85), "motorcycle": (1.10, 0.45, 0.80)}
MIN_HALF_WIDTH = 0.15

# 多样性配置:不同场景用不同天气
WEATHER_PRESETS = [
    "ClearNoon", "CloudyNoon", "WetNoon",
    "HardRainNoon", "ClearSunset", "WetSunset",
]

def classify_actor(actor):
    """CARLA actor → 训练类别"""
    if actor.type_id.startswith("walker."):
        return "pedestrian"
    base = actor.attributes.get("base_type", "")
    return BASE_TYPE_MAP.get(base, DEFAULT_CATEGORY)

def build_intrinsic(width, height, fov_deg):
    """内参矩阵(公式见 1.4 节)"""
    f = width / (2.0 * math.tan(math.radians(fov_deg) / 2.0))
    return [[f, 0.0, width / 2.0],
            [0.0, f, height / 2.0],
            [0.0, 0.0, 1.0]]

class BEVDataCollector:

    def __init__(self, host="localhost", port=2000):
        self.client = carla.Client(host, port)
        self.client.set_timeout(20.0)
        self.actors = []
        self.walker_ctrls = []     # 行人 AI 控制器(清理时要先 stop 再销毁)
        self.sensors = {}
        self.queues = {}
        self._orig = None

    # ---------------- 场景初始化 ----------------
    def setup_scene(self, town=None, weather=None, n_npc=40, n_walkers=30):
        if town:
            print(f"  加载地图 {town} ...")
            self.world = self.client.load_world(town)
        else:
            self.world = self.client.get_world()

        # 天气(增加数据多样性)
        if weather:
            self.world.set_weather(getattr(carla.WeatherParameters, weather))

        # 同步模式(1.2 节讲过,采数据必须开)
        self._orig = self.world.get_settings()
        s = self.world.get_settings()
        s.synchronous_mode = True
        s.fixed_delta_seconds = 1.0 / FPS
        self.world.apply_settings(s)

        self.tm = self.client.get_trafficmanager(8000)
        self.tm.set_synchronous_mode(True)

        bp_lib = self.world.get_blueprint_library()

        # --- 主车 ---
        v_bp = bp_lib.filter("vehicle.tesla.model3")[0]
        v_bp.set_attribute("role_name", "ego")
        spawns = self.world.get_map().get_spawn_points()
        random.shuffle(spawns)
        self.ego = None
        for sp in spawns:
            self.ego = self.world.try_spawn_actor(v_bp, sp)
            if self.ego:
                break
        if self.ego is None:
            raise RuntimeError("无法生成主车")
        # 记下出生点:同步模式下刚生成的 actor 在第一次 tick 前 get_location() 还是原点
        self.ego_loc = sp.location
        self.actors.append(self.ego)
        self.ego.set_autopilot(True, self.tm.get_port())

        # --- 相机 ---
        for name, cfg in CAMERA_RIG.items():
            bp = bp_lib.find("sensor.camera.rgb")
            bp.set_attribute("image_size_x", str(IMG_W))
            bp.set_attribute("image_size_y", str(IMG_H))
            bp.set_attribute("fov", str(cfg["fov"]))
            bp.set_attribute("sensor_tick", "0.0")
            tf = carla.Transform(
                carla.Location(x=cfg["x"], y=cfg["y"], z=cfg["z"]),
                carla.Rotation(yaw=cfg["yaw"]))
            cam = self.world.spawn_actor(bp, tf, attach_to=self.ego)
            q = queue.Queue()
            cam.listen(q.put)
            self.sensors[name] = cam
            self.queues[name] = q
            self.actors.append(cam)

        # --- 激光雷达 ---
        l_bp = bp_lib.find("sensor.lidar.ray_cast")
        l_bp.set_attribute("channels", "32")
        l_bp.set_attribute("range", str(PC_RANGE + 10))
        l_bp.set_attribute("points_per_second", "400000")
        l_bp.set_attribute("rotation_frequency", str(FPS))
        l_bp.set_attribute("upper_fov", "10")
        l_bp.set_attribute("lower_fov", "-30")
        l_bp.set_attribute("sensor_tick", "0.0")
        l_tf = carla.Transform(carla.Location(
            x=LIDAR_CFG["x"], y=LIDAR_CFG["y"], z=LIDAR_CFG["z"]))
        self.lidar = self.world.spawn_actor(l_bp, l_tf, attach_to=self.ego)
        self.lidar_queue = queue.Queue()
        self.lidar.listen(self.lidar_queue.put)
        self.actors.append(self.lidar)

        # --- NPC 车流 ---
        self._spawn_npc(n_npc)
        # --- 行人 ---
        # [修正] 原版只生成车辆,pedestrian 类别永远是 0 个框
        self._spawn_walkers(n_walkers)

    def _spawn_npc(self, n):
        bp_lib = self.world.get_blueprint_library()
        vehicles = list(bp_lib.filter("vehicle.*"))
        # [v3] 两轮车单独成池,按 TWO_WHEEL_RATIO 的比例抽,保证 bicycle / motorcycle 有样本
        two_wheel = [b for b in vehicles if b.has_attribute("base_type") and
                     b.get_attribute("base_type").as_str() in ("bicycle", "motorcycle")]
        two_ids = {b.id for b in two_wheel}
        four_wheel = [b for b in vehicles if b.id not in two_ids]
        spawns = self.world.get_map().get_spawn_points()
        # [v3] 按离主车的距离排序,从近往远放车:车流集中在主车周围,每帧框数明显增加
        spawns.sort(key=lambda sp: sp.location.distance(self.ego_loc))
        cnt = 0
        for sp in spawns:
            if cnt >= n:
                break
            pool = two_wheel if (two_wheel and random.random() < TWO_WHEEL_RATIO) else four_wheel
            npc = self.world.try_spawn_actor(random.choice(pool), sp)
            if npc:
                npc.set_autopilot(True, self.tm.get_port())
                self.actors.append(npc)
                cnt += 1
        print(f"  生成 {cnt} 辆 NPC")

    def _spawn_walkers(self, n):
        """生成行人 + AI 控制器(写法与 CARLA 自带 generate_traffic.py 一致)"""
        bp_lib = self.world.get_blueprint_library()
        walker_bps = bp_lib.filter("walker.pedestrian.*")
        ctrl_bp = bp_lib.find("controller.ai.walker")

        batch = []
        # [v3] 只在主车周围 WALKER_RADIUS 米内放行人(全图随机撒的话几乎都在感知范围外)
        locs, tries = [], 0
        while len(locs) < n and tries < n * 100:
            tries += 1
            loc = self.world.get_random_location_from_navigation()
            if loc is not None and loc.distance(self.ego_loc) < WALKER_RADIUS:
                locs.append(loc)
        for loc in locs:
            bp = random.choice(walker_bps)
            if bp.has_attribute("is_invincible"):
                bp.set_attribute("is_invincible", "false")
            batch.append(carla.command.SpawnActor(bp, carla.Transform(loc)))
        res = self.client.apply_batch_sync(batch, True)
        walker_ids = [r.actor_id for r in res if not r.error]

        # 每个行人挂一个 AI 控制器
        batch = [carla.command.SpawnActor(ctrl_bp, carla.Transform(), wid)
                 for wid in walker_ids]
        res = self.client.apply_batch_sync(batch, True)
        ctrl_ids = [r.actor_id for r in res if not r.error]

        self.world.tick()   # 同步模式下控制器要先 tick 一次才能 start
        for cid in ctrl_ids:
            c = self.world.get_actor(cid)
            c.start()
            c.go_to_location(self.world.get_random_location_from_navigation())
            c.set_max_speed(1.0 + random.random())   # 1~2 m/s
            self.walker_ctrls.append(c)
        self.actors += [self.world.get_actor(i) for i in walker_ids]
        print(f"  生成 {len(walker_ids)} 个行人")

    # ---------------- 真值提取(本节核心) ----------------
    def extract_boxes(self, lidar_points_ego):
        """
        提取当前帧所有可见目标的 3D 框(自车坐标系)

        返回格式(每个框):
            center : [x, y, z]   自车系下的框中心
            size   : [l, w, h]   长宽高(注意是全尺寸,不是半尺寸)
            yaw    : float       朝向(弧度,自车系)
            category, num_lidar_pts, distance
        """
        ego_tf = self.ego.get_transform()
        # 世界 → 自车 的逆变换矩阵
        world2ego = np.array(ego_tf.get_inverse_matrix())

        boxes, rejected = [], []
        candidates = list(self.world.get_actors().filter("vehicle.*"))
        candidates += list(self.world.get_actors().filter("walker.*"))

        for actor in candidates:
            # 排除自车(易漏,见本节说明)
            if actor.id == self.ego.id:
                continue

            bbox = actor.bounding_box
            actor_tf = actor.get_transform()
            category = classify_actor(actor)
            half = (bbox.extent.x, bbox.extent.y, bbox.extent.z)

            # 框中心:局部偏移 → 世界系
            center_world = actor_tf.transform(bbox.location)
            fixed = False
            if category in TWO_WHEEL_HALF_SIZE and min(half[0], half[1]) < MIN_HALF_WIDTH:
                # [v4] 扁框:用典型尺寸,框底放在车辆原点(地面)上
                half = TWO_WHEEL_HALF_SIZE[category]
                center_world = carla.Location(actor_tf.location.x, actor_tf.location.y,
                                              actor_tf.location.z + half[2])
                fixed = True
            p = np.array([center_world.x, center_world.y, center_world.z, 1.0])

            # 世界系 → 自车系
            p_ego = world2ego @ p
            x, y, z = float(p_ego[0]), float(p_ego[1]), float(p_ego[2])

            # --- 过滤规则 ①: 超出 BEV 范围 ---
            if abs(x) > PC_RANGE or abs(y) > PC_RANGE:
                continue

            # 朝向:相对自车的 yaw
            yaw = math.radians(actor_tf.rotation.yaw - ego_tf.rotation.yaw)
            # 归一化到 [-pi, pi]
            yaw = math.atan2(math.sin(yaw), math.cos(yaw))

            # --- 过滤规则 ③: 激光雷达点数(间接判断遮挡)---
            n_pts = self._count_points_in_box(lidar_points_ego, (x, y, z), half, yaw)

            rec = {
                "category": category,
                "center": [round(x, 3), round(y, 3), round(z, 3)],
                # extent 是半尺寸,×2 得全尺寸(易错点)
                "size": [round(half[0] * 2, 3), round(half[1] * 2, 3), round(half[2] * 2, 3)],
                "yaw": round(yaw, 4),
                "num_lidar_pts": int(n_pts),
                "distance": round(math.sqrt(x*x + y*y), 2),
                "actor_id": int(actor.id),   # 跨帧跟踪用
            }
            if fixed:
                rec["size_fixed"] = True
            if n_pts < 5:
                # [v4] 不丢掉,记下来:调试时能看到"在范围内、但被判为不可见"的目标
                rejected.append(rec)
                continue
            boxes.append(rec)

        return boxes, rejected

    @staticmethod
    def _count_points_in_box(pts, center, half_size, yaw):
        """
        统计落在 3D 框内的激光点数量

        做法:把点云转到框的局部坐标系,再做轴对齐判断(简单可靠)
        """
        if pts is None or len(pts) == 0:
            return 0

        cx, cy, cz = center
        hx, hy, hz = half_size

        # 粗筛:先用外接球快速排除大部分点(性能优化)
        r = math.sqrt(hx*hx + hy*hy + hz*hz) + 0.5
        d = pts[:, :3] - np.array([cx, cy, cz])
        near = np.sum(d * d, axis=1) < r * r
        if not np.any(near):
            return 0
        d = d[near]

        # 反向旋转到框的局部系
        c, s = math.cos(-yaw), math.sin(-yaw)
        lx = d[:, 0] * c - d[:, 1] * s
        ly = d[:, 0] * s + d[:, 1] * c
        lz = d[:, 2]

        inside = ((np.abs(lx) <= hx) &
                  (np.abs(ly) <= hy) &
                  (np.abs(lz) <= hz))
        return int(np.sum(inside))

    # ---------------- 标定导出 ----------------
    def export_calib(self):
        """导出内参与外参(一个场景内固定)"""
        calib = {"cameras": {}, "lidar": {}}

        for name, cfg in CAMERA_RIG.items():
            calib["cameras"][name] = {
                "intrinsic": build_intrinsic(IMG_W, IMG_H, cfg["fov"]),
                # 外参:相机相对自车的位姿
                "translation": [cfg["x"], cfg["y"], cfg["z"]],
                "rotation_yaw_deg": cfg["yaw"],
                "fov": cfg["fov"],
                "image_size": [IMG_W, IMG_H],
            }

        calib["lidar"] = {
            "translation": [LIDAR_CFG["x"], LIDAR_CFG["y"], LIDAR_CFG["z"]],
            "rotation_yaw_deg": 0.0,
        }
        return calib

    # ---------------- 采集主循环 ----------------
    def collect(self, scene_dir, n_frames, warmup=20):
        os.makedirs(scene_dir, exist_ok=True)
        for name in CAMERA_RIG:
            os.makedirs(os.path.join(scene_dir, name), exist_ok=True)
        os.makedirs(os.path.join(scene_dir, "LIDAR_TOP"), exist_ok=True)

        # 标定单独存
        with open(os.path.join(scene_dir, "calib.json"), "w") as f:
            json.dump(self.export_calib(), f, indent=2)

        # 预热(丢弃,让物理和车流稳定)
        for _ in range(warmup):
            self.world.tick()
            for q in self.queues.values():
                q.get(timeout=10)
            self.lidar_queue.get(timeout=10)

        frames_meta = []
        for i in range(n_frames):
            frame_id = self.world.tick()

            # 取本帧所有传感器数据(帧号校验,见 1.2 节)
            images = {n: self._take(q, frame_id)
                      for n, q in self.queues.items()}
            pcd = self._take(self.lidar_queue, frame_id)

            # --- 存图像 ---
            for name, img in images.items():
                img.save_to_disk(os.path.join(scene_dir, name, f"{i:06d}.jpg"))

            # --- 存点云(裸 float32,np.fromfile 可读)---
            pts = np.frombuffer(pcd.raw_data, dtype=np.float32).reshape(-1, 4)
            pts.tofile(os.path.join(scene_dir, "LIDAR_TOP", f"{i:06d}.bin"))

            # --- 提取 3D 框真值 ---
            # 注意:点云在雷达系,框在自车系,做个平移对齐
            pts_ego = pts[:, :3].copy()
            pts_ego[:, 2] += LIDAR_CFG["z"]
            boxes, rejected = self.extract_boxes(pts_ego)

            # --- 自车位姿 ---
            tf = self.ego.get_transform()
            vel = self.ego.get_velocity()

            frames_meta.append({
                "index": i,
                "carla_frame": int(frame_id),
                "timestamp": round(i / FPS, 4),
                "ego_pose": {
                    "translation": [round(tf.location.x, 3),
                                    round(tf.location.y, 3),
                                    round(tf.location.z, 3)],
                    "rotation": [round(tf.rotation.roll, 3),
                                 round(tf.rotation.pitch, 3),
                                 round(tf.rotation.yaw, 3)],
                },
                "ego_speed": round(3.6 * math.sqrt(
                    vel.x**2 + vel.y**2 + vel.z**2), 2),
                "num_lidar_points": int(pts.shape[0]),
                "boxes": boxes,
                "rejected": rejected,     # 范围内但激光点 < 5 的目标(训练时不用)
            })

            if (i + 1) % 25 == 0:
                avg = np.mean([len(f["boxes"]) for f in frames_meta])
                print(f"    {i+1}/{n_frames} 帧, 平均每帧 {avg:.1f} 个框")

        with open(os.path.join(scene_dir, "frames.json"), "w") as f:
            json.dump({"fps": FPS, "pc_range": PC_RANGE,
                       "frames": frames_meta}, f)

        # [v4] 按类别汇总:保留了多少、因激光点太少被丢了多少
        kept = Counter(b["category"] for f in frames_meta for b in f["boxes"])
        drop = Counter(b["category"] for f in frames_meta for b in f["rejected"])
        print("    类别统计(保留 / 范围内但被过滤):")
        for c in ("car", "pedestrian", "bicycle", "motorcycle"):
            print(f"      {c:<11s} {kept.get(c, 0):>5d} / {drop.get(c, 0):>5d}")

        total_boxes = sum(len(f["boxes"]) for f in frames_meta)
        return {"n_frames": n_frames, "n_boxes": total_boxes}

    def _take(self, q, frame_id, timeout=10.0):
        while True:
            data = q.get(timeout=timeout)
            if data.frame == frame_id:
                return data
            if data.frame > frame_id:
                raise RuntimeError("传感器帧号超前,同步异常")

    # ---------------- 清理 ----------------
    def cleanup(self):
        for c in self.walker_ctrls:
            try: c.stop()
            except Exception: pass
        if self.walker_ctrls:
            self.client.apply_batch([carla.command.DestroyActor(c) for c in self.walker_ctrls])
        self.walker_ctrls.clear()
        for s in list(self.sensors.values()) + [getattr(self, "lidar", None)]:
            if s is None:
                continue
            try: s.stop()
            except Exception: pass
        if self.actors:
            self.client.apply_batch(
                [carla.command.DestroyActor(a) for a in self.actors if a])
        self.actors.clear()
        self.sensors.clear()
        self.queues.clear()
        if self._orig:
            self.world.apply_settings(self._orig)
        try: self.tm.set_synchronous_mode(False)
        except Exception: pass

def main():
    ap = argparse.ArgumentParser()
    ap.add_argument("--scenes", type=int, default=3)
    ap.add_argument("--frames", type=int, default=100)
    ap.add_argument("--npc", type=int, default=40)
    ap.add_argument("--walkers", type=int, default=30)
    ap.add_argument("--out", default="./dataset")
    ap.add_argument("--towns", nargs="+",
                    default=["Town03", "Town05", "Town10HD"])
    args = ap.parse_args()

    os.makedirs(args.out, exist_ok=True)
    scene_infos = []

    for si in range(args.scenes):
        town = args.towns[si % len(args.towns)]
        weather = WEATHER_PRESETS[si % len(WEATHER_PRESETS)]
        scene_name = f"scene_{si:04d}"
        print(f"\n[{si+1}/{args.scenes}] {scene_name} | {town} | {weather}")

        collector = BEVDataCollector()
        try:
            collector.setup_scene(town=town, weather=weather, n_npc=args.npc,
                                  n_walkers=args.walkers)
            stat = collector.collect(
                os.path.join(args.out, scene_name), args.frames)
            scene_infos.append({
                "name": scene_name, "town": town, "weather": weather,
                **stat})
            print(f"  完成: {stat['n_frames']} 帧, {stat['n_boxes']} 个框")
        except Exception as e:
            print(f"  ✗ 场景失败: {e}")
        finally:
            collector.cleanup()

    # 全局元信息
    with open(os.path.join(args.out, "dataset_info.json"), "w") as f:
        json.dump({
            "scenes": scene_infos,
            "categories": ["car", "pedestrian", "bicycle", "motorcycle"],
            "camera_rig": CAMERA_RIG,
            "lidar_cfg": LIDAR_CFG,
            "image_size": [IMG_W, IMG_H],
            "fps": FPS,
            "pc_range": PC_RANGE,
        }, f, indent=2)

    total_f = sum(s["n_frames"] for s in scene_infos)
    total_b = sum(s["n_boxes"] for s in scene_infos)
    print(f"\n采集完成: {len(scene_infos)} 个场景, "
          f"{total_f} 帧, {total_b} 个标注框")
    print(f"输出目录: {args.out}")

if __name__ == "__main__":
    main()
check_frame_v4.py
#!/usr/bin/env python3
"""
2.1 采集结果自检:把一帧数据"画出来"

用法:
    python check_frame.py ./dataset/scene_0000 --frame 30

输出(存在 scene 目录下的 _check/ 里):
    bev_000030.png     鸟瞰图:激光点 + 3D 框(俯视),自车在中心;虚线框 = 被过滤的目标(旁边数字是框内激光点数)
    front_000030.png   前视图:把 3D 框的 8 个角点投影到 CAM_FRONT 图像上
并在终端打印本场景各类别的框数量。

看什么:
    ① 鸟瞰图里,每个框里应该有一团激光点 → 坐标系、平移、朝向都对
    ② 前视图里,框应该套住画面里的车/人 → 内参、外参、投影都对
    ③ 类别统计里 pedestrian、bicycle 不应为 0 → 采集配置没漏
"""
import argparse
import json
import math
import os
from collections import Counter

import numpy as np
import matplotlib
matplotlib.use("Agg")
import matplotlib.pyplot as plt
from PIL import Image, ImageDraw

COLORS = {"car": "#38bdf8", "pedestrian": "#f87171",
          "bicycle": "#4ade80", "motorcycle": "#fbbf24"}
LIDAR_Z = 2.5   # 与采集脚本 LIDAR_CFG["z"] 一致

def box_corners(center, size, yaw):
    """3D 框 → 8 个角点(自车系,CARLA 约定:x 前、y 右、z 上)"""
    l, w, h = size
    xs = np.array([1, 1, -1, -1, 1, 1, -1, -1]) * l / 2
    ys = np.array([1, -1, -1, 1, 1, -1, -1, 1]) * w / 2
    zs = np.array([1, 1, 1, 1, -1, -1, -1, -1]) * h / 2
    c, s = math.cos(yaw), math.sin(yaw)
    x = xs * c - ys * s + center[0]
    y = xs * s + ys * c + center[1]
    z = zs + center[2]
    return np.stack([x, y, z], 1)

def ego_to_pixel(pts, cam):
    """
    自车系点 → 像素坐标。这是手撕第 4 题的 CARLA 版本:
      1) 减去相机安装位置,再绕 z 轴转 -yaw     → 相机系(仍是 x 前 y 右 z 上)
      2) 换成针孔模型的轴:X=右=y, Y=下=-z, Z=前=x
      3) u = f·X/Z + cx,  v = f·Y/Z + cy
    """
    t = np.array(cam["translation"])
    a = -math.radians(cam["rotation_yaw_deg"])
    d = pts - t
    xc = d[:, 0] * math.cos(a) - d[:, 1] * math.sin(a)
    yc = d[:, 0] * math.sin(a) + d[:, 1] * math.cos(a)
    zc = d[:, 2]
    K = np.array(cam["intrinsic"])
    X, Y, Z = yc, -zc, xc
    u = K[0, 0] * X / np.clip(Z, 1e-6, None) + K[0, 2]
    v = K[1, 1] * Y / np.clip(Z, 1e-6, None) + K[1, 2]
    return np.stack([u, v], 1), Z

NEAR = 0.3   # 近裁剪面(米):只画相机前方 0.3 m 以外的部分

def project_edge(p0, p1, cam):
    """
    投影一条棱。两端都在相机前方:直接投影;一端在相机背后:先在 3D 里截到近裁剪面再投影;
    两端都在背后:不画。不做这一步的话,贴着自车的大车(侧面、半出画面)会整个画不出来。
    """
    seg = np.stack([p0, p1])
    _, depth = ego_to_pixel(seg, cam)
    if (depth < NEAR).all():
        return None
    if (depth < NEAR).any():
        t = (NEAR - depth[0]) / (depth[1] - depth[0])
        cut = p0 + t * (p1 - p0)
        seg = np.stack([cut, p1]) if depth[0] < NEAR else np.stack([p0, cut])
    uv, _ = ego_to_pixel(seg, cam)
    return uv

def draw_bev(pts, boxes, rng, out, rejected=()):
    fig, ax = plt.subplots(figsize=(7, 7), facecolor="#0d1117")
    ax.set_facecolor("#0d1117")
    m = (np.abs(pts[:, 0]) < rng) & (np.abs(pts[:, 1]) < rng)
    # 横轴 = y(右为正),纵轴 = x(前为正),和你坐在车里看到的方向一致
    ax.scatter(pts[m, 1], pts[m, 0], s=0.3, c=pts[m, 2], cmap="viridis", vmin=-0.5, vmax=3)
    for b in boxes:
        cs = box_corners(b["center"], b["size"], b["yaw"])[:4]
        poly = np.vstack([cs, cs[:1]])
        col = COLORS.get(b["category"], "w")
        ax.plot(poly[:, 1], poly[:, 0], color=col, lw=1.4)
        # 车头方向线:从中心指向前沿中点
        front = (cs[0] + cs[1]) / 2
        ax.plot([b["center"][1], front[1]], [b["center"][0], front[0]], color=col, lw=1)
    for b in rejected:   # 被过滤的目标:虚线,旁边标激光点数
        cs = box_corners(b["center"], b["size"], b["yaw"])[:4]
        poly = np.vstack([cs, cs[:1]])
        ax.plot(poly[:, 1], poly[:, 0], color=COLORS.get(b["category"], "w"), lw=0.9, ls="--", alpha=0.7)
        ax.text(b["center"][1] + 1, b["center"][0], str(b["num_lidar_pts"]), color="#9aabbc", fontsize=6)
    ax.add_patch(plt.Rectangle((-1, -2.3), 2, 4.6, color="w"))       # 自车
    ax.set_xlim(-rng, rng); ax.set_ylim(-rng, rng); ax.set_aspect("equal")
    ax.tick_params(colors="#9aabbc")
    ax.set_xlabel("y  (m, right +)", color="#9aabbc"); ax.set_ylabel("x  (m, forward +)", color="#9aabbc")
    for k, c in COLORS.items():
        ax.plot([], [], color=c, label=k)
    ax.legend(loc="upper right", facecolor="#161e2b", labelcolor="w", fontsize=8)
    fig.savefig(out, dpi=110, bbox_inches="tight"); plt.close(fig)

def draw_front(img_path, cam, boxes, out):
    im = Image.open(img_path).convert("RGB")
    dr = ImageDraw.Draw(im)
    edges = [(0, 1), (1, 2), (2, 3), (3, 0), (4, 5), (5, 6), (6, 7), (7, 4),
             (0, 4), (1, 5), (2, 6), (3, 7)]
    n = 0
    for b in boxes:
        cs = box_corners(b["center"], b["size"], b["yaw"])
        segs = [project_edge(cs[i], cs[j], cam) for i, j in edges]
        segs = [g for g in segs if g is not None]
        if not segs:
            continue
        allp = np.vstack(segs)
        if (allp[:, 0].max() < 0 or allp[:, 0].min() > im.width or
                allp[:, 1].max() < 0 or allp[:, 1].min() > im.height):
            continue
        col = COLORS.get(b["category"], "#ffffff")
        for g in segs:
            dr.line([tuple(g[0]), tuple(g[1])], fill=col, width=2)
        n += 1
    im.save(out)
    return n

def main():
    ap = argparse.ArgumentParser()
    ap.add_argument("scene_dir")
    ap.add_argument("--frame", type=int, default=0)
    ap.add_argument("--cam", default="CAM_FRONT")
    args = ap.parse_args()

    meta = json.load(open(os.path.join(args.scene_dir, "frames.json")))
    calib = json.load(open(os.path.join(args.scene_dir, "calib.json")))
    fr = meta["frames"][args.frame]
    tag = f"{args.frame:06d}"

    pts = np.fromfile(os.path.join(args.scene_dir, "LIDAR_TOP", f"{tag}.bin"),
                      dtype=np.float32).reshape(-1, 4)[:, :3].copy()
    pts[:, 2] += LIDAR_Z          # 雷达系 → 自车系(与采集脚本相同的对齐)

    out_dir = os.path.join(args.scene_dir, "_check"); os.makedirs(out_dir, exist_ok=True)
    draw_bev(pts, fr["boxes"], meta.get("pc_range", 51.2), os.path.join(out_dir, f"bev_{tag}.png"),
             fr.get("rejected", []))
    n_drawn = draw_front(os.path.join(args.scene_dir, args.cam, f"{tag}.jpg"),
                         calib["cameras"][args.cam], fr["boxes"],
                         os.path.join(out_dir, f"{args.cam.lower()}_{tag}.png"))

    cnt = Counter(b["category"] for f in meta["frames"] for b in f["boxes"])
    rej = Counter(b["category"] for f in meta["frames"] for b in f.get("rejected", []))
    print(f"第 {args.frame} 帧:{len(fr['boxes'])} 个框,其中 {n_drawn} 个落在 {args.cam} 画面内"
          f";另有 {len(fr.get('rejected', []))} 个因激光点 < 5 被过滤(鸟瞰图里的虚线框)")
    print("整个场景各类别框数:", dict(cnt))
    if rej:
        print("整个场景被过滤的目标:", dict(rej))
    for k in ("pedestrian", "bicycle", "motorcycle"):
        if cnt.get(k, 0) == 0:
            print(f"  ⚠ {k} 为 0:检查是否生成了这类目标(行人需要 --walkers)")
    pts_in = [b["num_lidar_pts"] for b in fr["boxes"]]
    if pts_in:
        print(f"每个框内激光点数:最少 {min(pts_in)},中位数 {int(np.median(pts_in))}")
    print(f"图片已保存到 {out_dir}")

if __name__ == "__main__":
    main()
请这样再跑一次
python collect_bev_dataset_v4.py --scenes 1 --frames 50 --npc 60 --walkers 40 --towns Town10HD --out ./dataset_v4
python check_frame_v4.py ./dataset_v4/scene_0000 --frame 20
执行结果:
(ad) leoking@leoking-desktop:~/carla/work/courses/M2$ python collect_bev_dataset_v4.py --scenes 1 --frames 50 --npc 60 --walkers 40 --towns Town10HD --out ./dataset_v4

[1/1] scene_0000 | Town10HD | ClearNoon
  加载地图 Town10HD ...
  生成 60 辆 NPC
  生成 39 个行人
    25/50 帧, 平均每帧 17.4 个框
    50/50 帧, 平均每帧 15.5 个框
    类别统计(保留 / 范围内但被过滤):
      car           684 /   122
      pedestrian      0 /  1293
      bicycle         0 /    24
      motorcycle     91 /    70
  完成: 50 帧, 775 个框

采集完成: 1 个场景, 50 帧, 775 个标注框
输出目录: ./dataset_v4

---
(ad) leoking@leoking-desktop:~/carla/work/courses/M2$ python check_frame_v4.py ./dataset_v4/scene_0000 --frame 20
第 20 帧:18 个框,其中 6 个落在 CAM_FRONT 画面内;另有 31 个因激光点 < 5 被过滤(鸟瞰图里的虚线框)
整个场景各类别框数: {'car': 684, 'motorcycle': 91}
整个场景被过滤的目标: {'bicycle': 24, 'car': 122, 'motorcycle': 70, 'pedestrian': 1293}
  ⚠ pedestrian 为 0:检查是否生成了这类目标(行人需要 --walkers)
  ⚠ bicycle 为 0:检查是否生成了这类目标(行人需要 --walkers)
每个框内激光点数:最少 5,中位数 31
图片已保存到 ./dataset_v4/scene_0000/_check
(ad) leoking@leoking-desktop:~/carla/work/courses/M2$
为者常成,行者常至
自由转载-非商用-非衍生-保持署名(创意共享3.0许可证)


